News World
Two open answers to jev's idea
Hello,
Last week, Jev made typed decisions (pick an option, say yes or no), but only on TypeSafe's servers, in the United States, with unpublished weights. This week, two open answers to the same idea: Splash has a Qwen model answer on your Mac, AnyJev makes an open model's probabilities reliable, and the problem of the week locks up an agent that has too many rights.
Releases
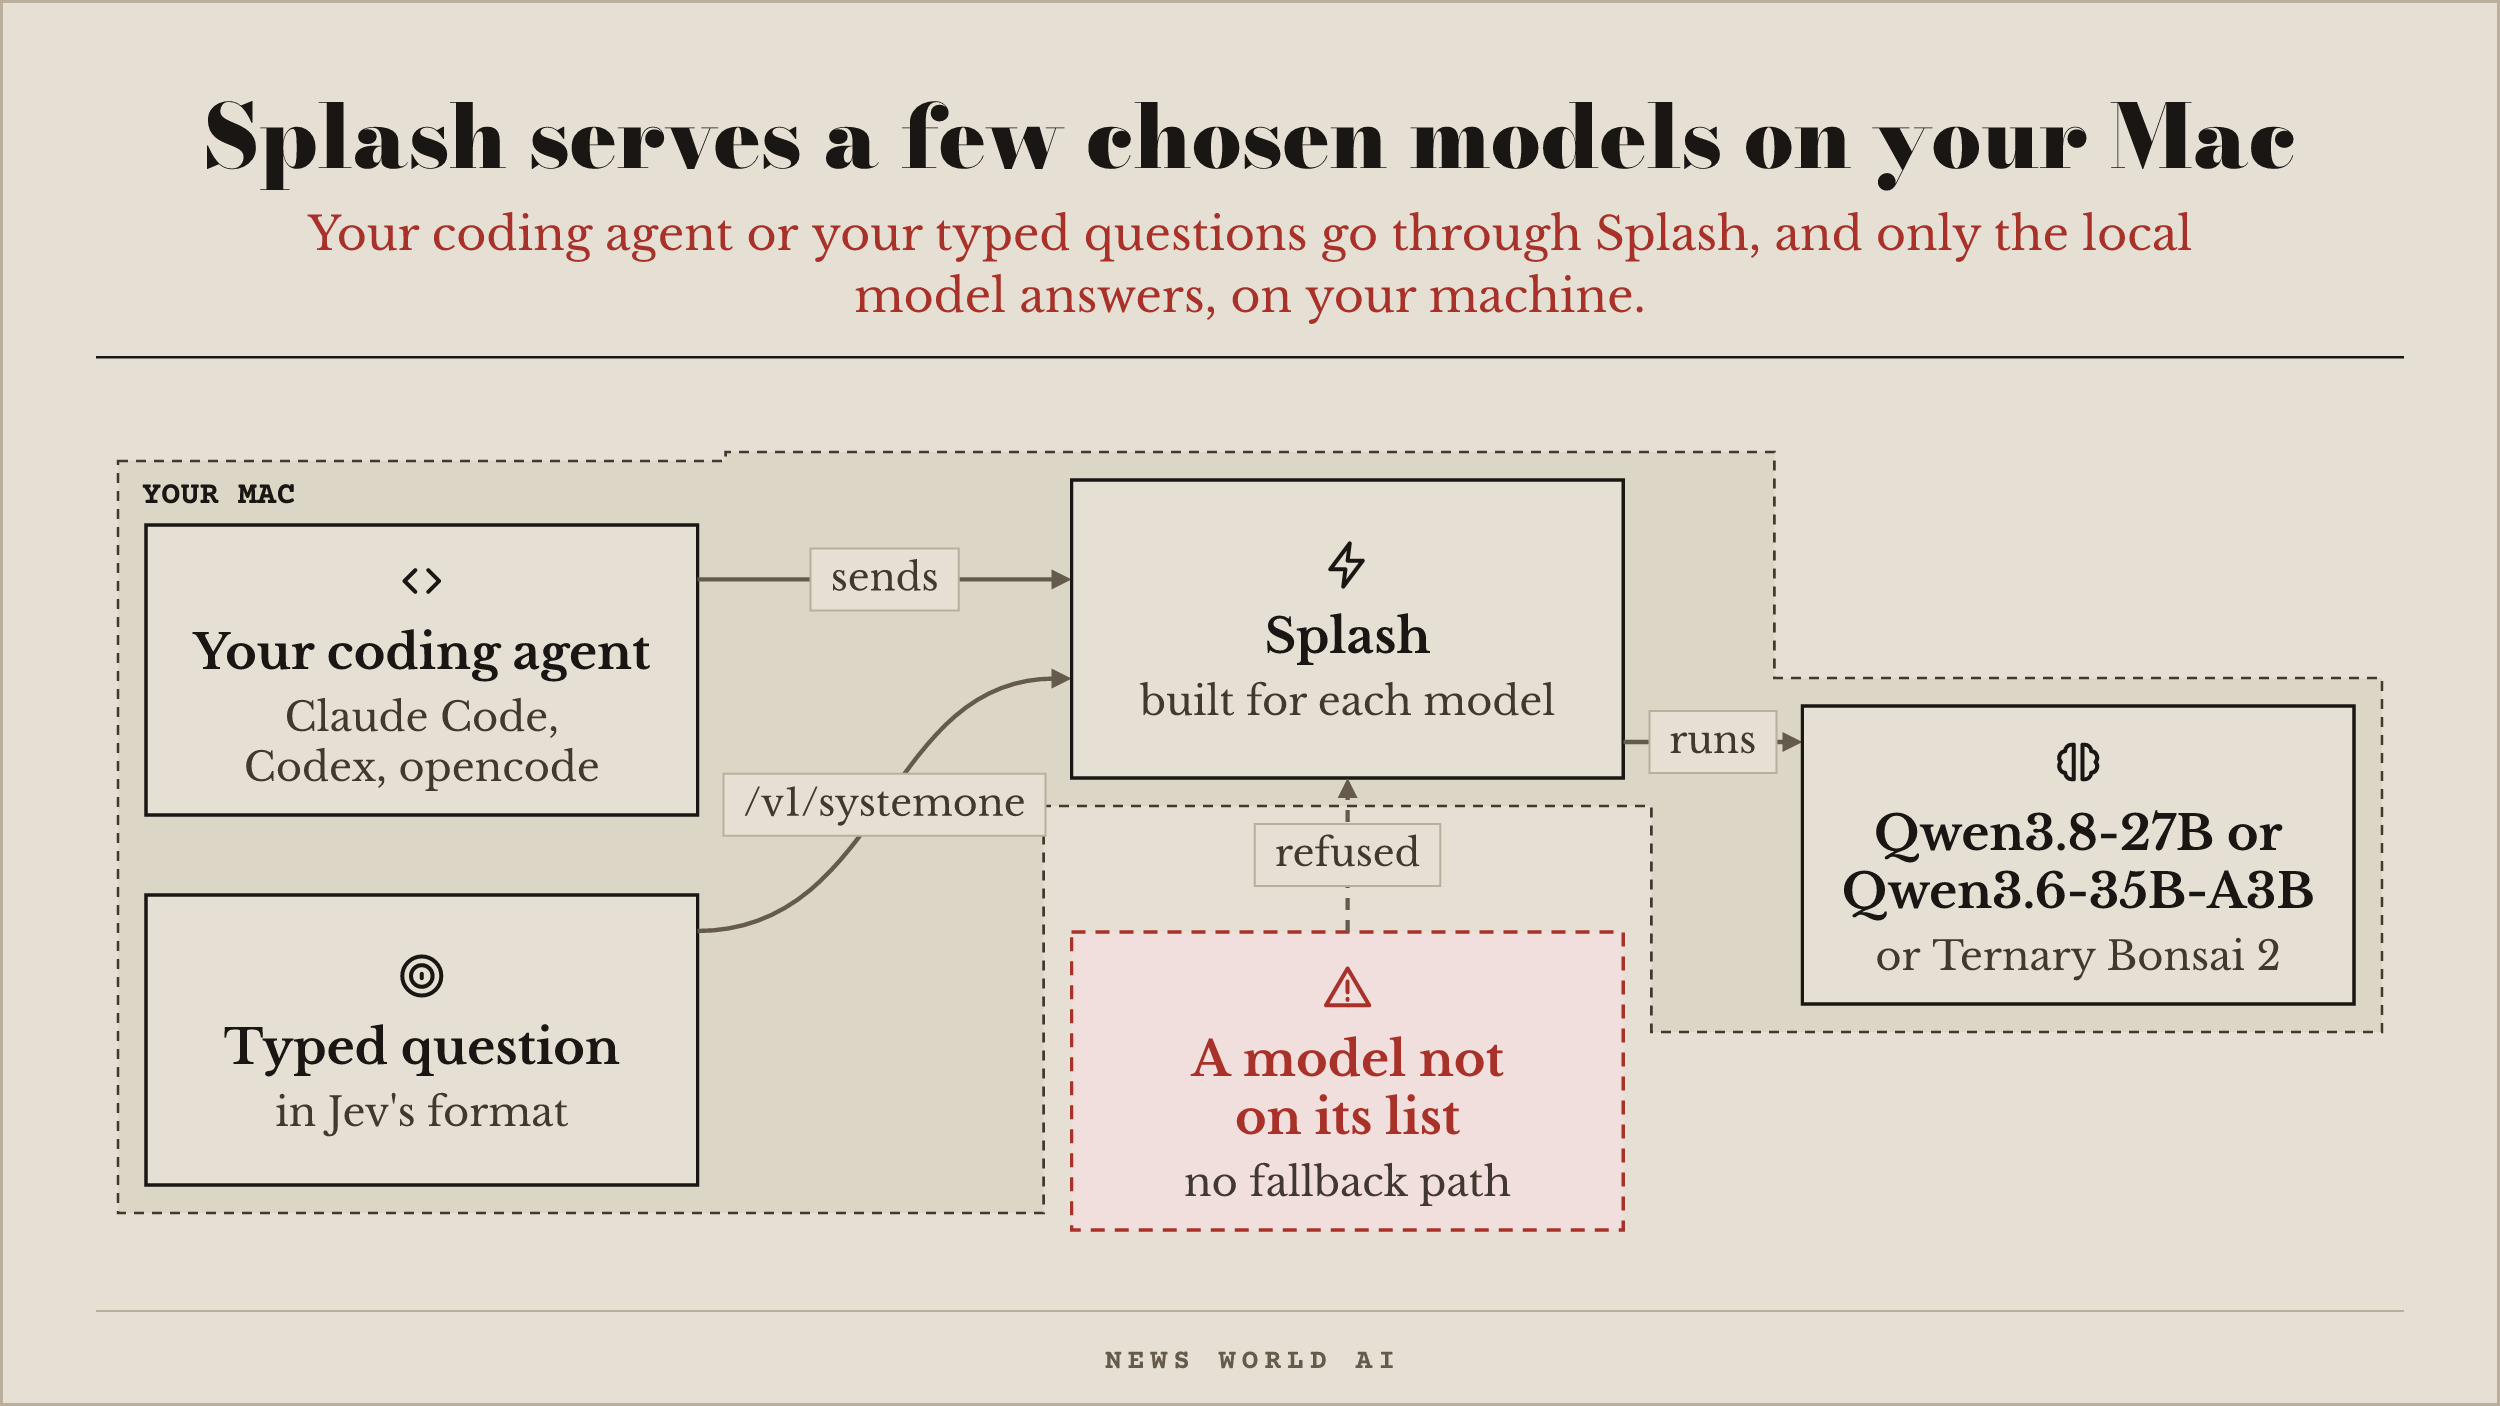
Splash (Inco AI)
Repository ★ 967, Apache-2.0, last commit on September 28, 2026.
What it's for Running a coding agent on a model that lives on your Mac: splash claude, splash codex or splash opencode starts it already wired up. At /v1/systemone, it also accepts typed questions in Jev's format through TypeSafe's official kit: Qwen answers them, locally, not Jev. It is built for two families of Qwen models, Qwen3.8-27B and Qwen3.6-35B-A3B (17.4 and 20.9 GB downloads), and also accepts Prism ML's Ternary Bonsai 2. According to Inco AI, on a 48 GB M5 Pro Mac with coding requests, the 27B writes a short answer at 74 tokens per second (a token is a piece of a word), twice as fast as the quickest of the other engines measured, and 1.2 times when reading a long fresh text (32,000 tokens). It needs an M3 Mac or newer, macOS 26.4 and 36 GB of memory, 24 GB with smaller versions.
The limit It only runs the models on its list. The benchmarks are Inco AI's own, on a single machine, with no independent measurement published. And the confidence /v1/systemone returns is not calibrated, the repository says: it is the naive reading whose flaws AnyJev measures.
Qwen3.8 27B (Qwen)
6,844,348 downloads, 16,510 likes on Hugging Face, Apache-2.0.
What it's for An open model that reads text and images, runs on your own machine without sending anything out, and whose license allows use in a commercial product. For an ordinary computer, ISTA publishes a compressed version in GGUF format (the llama.cpp format), downloaded 1,655,818 times. On a Mac, it is also one of the models Splash serves.
The limit The compressed version does not match the original everywhere. According to ISTA, its IQ3_S variant (11.8 GB instead of 53.8 GB) equals the original model on a math test (AIME25) and a coding test (LiveCodeBench v6), but loses 0.51 points on a science test (GPQA-Diamond).
GPT-6 Sol and Luna (OpenAI)
OpenAI's two faster, cheaper GPT-6 models, alongside Astra.
What it's for The work you already hand to OpenAI's models. Per million tokens, Sol costs $2 for input and $10 for output, Luna $0.10 and $0.50. According to OpenAI, Sol makes about half as many mistakes as its predecessor on its internal factuality test.
The limit Price and capabilities are OpenAI's claims alone: no independent benchmark confirms them yet.
MiMo V2.6 Pro RL (Xiaomi)
76,518 downloads, 587 likes on Hugging Face, MIT license.
What it's for Running an agent that understands text, images, video and audio, on a model whose weights Xiaomi publishes under a license that allows commercial use. There is also a lighter Flash version (309 billion parameters, 28,842 downloads). A plugin promising this model "free and unlimited", with no key and no account, is circulating on GitHub: the model is downloaded from Xiaomi, nowhere else.
The limit It is not a model for an ordinary computer: 1,020 billion parameters in total, 42 billion of which work on each word. The scores on its model card are published by Xiaomi.
Repos
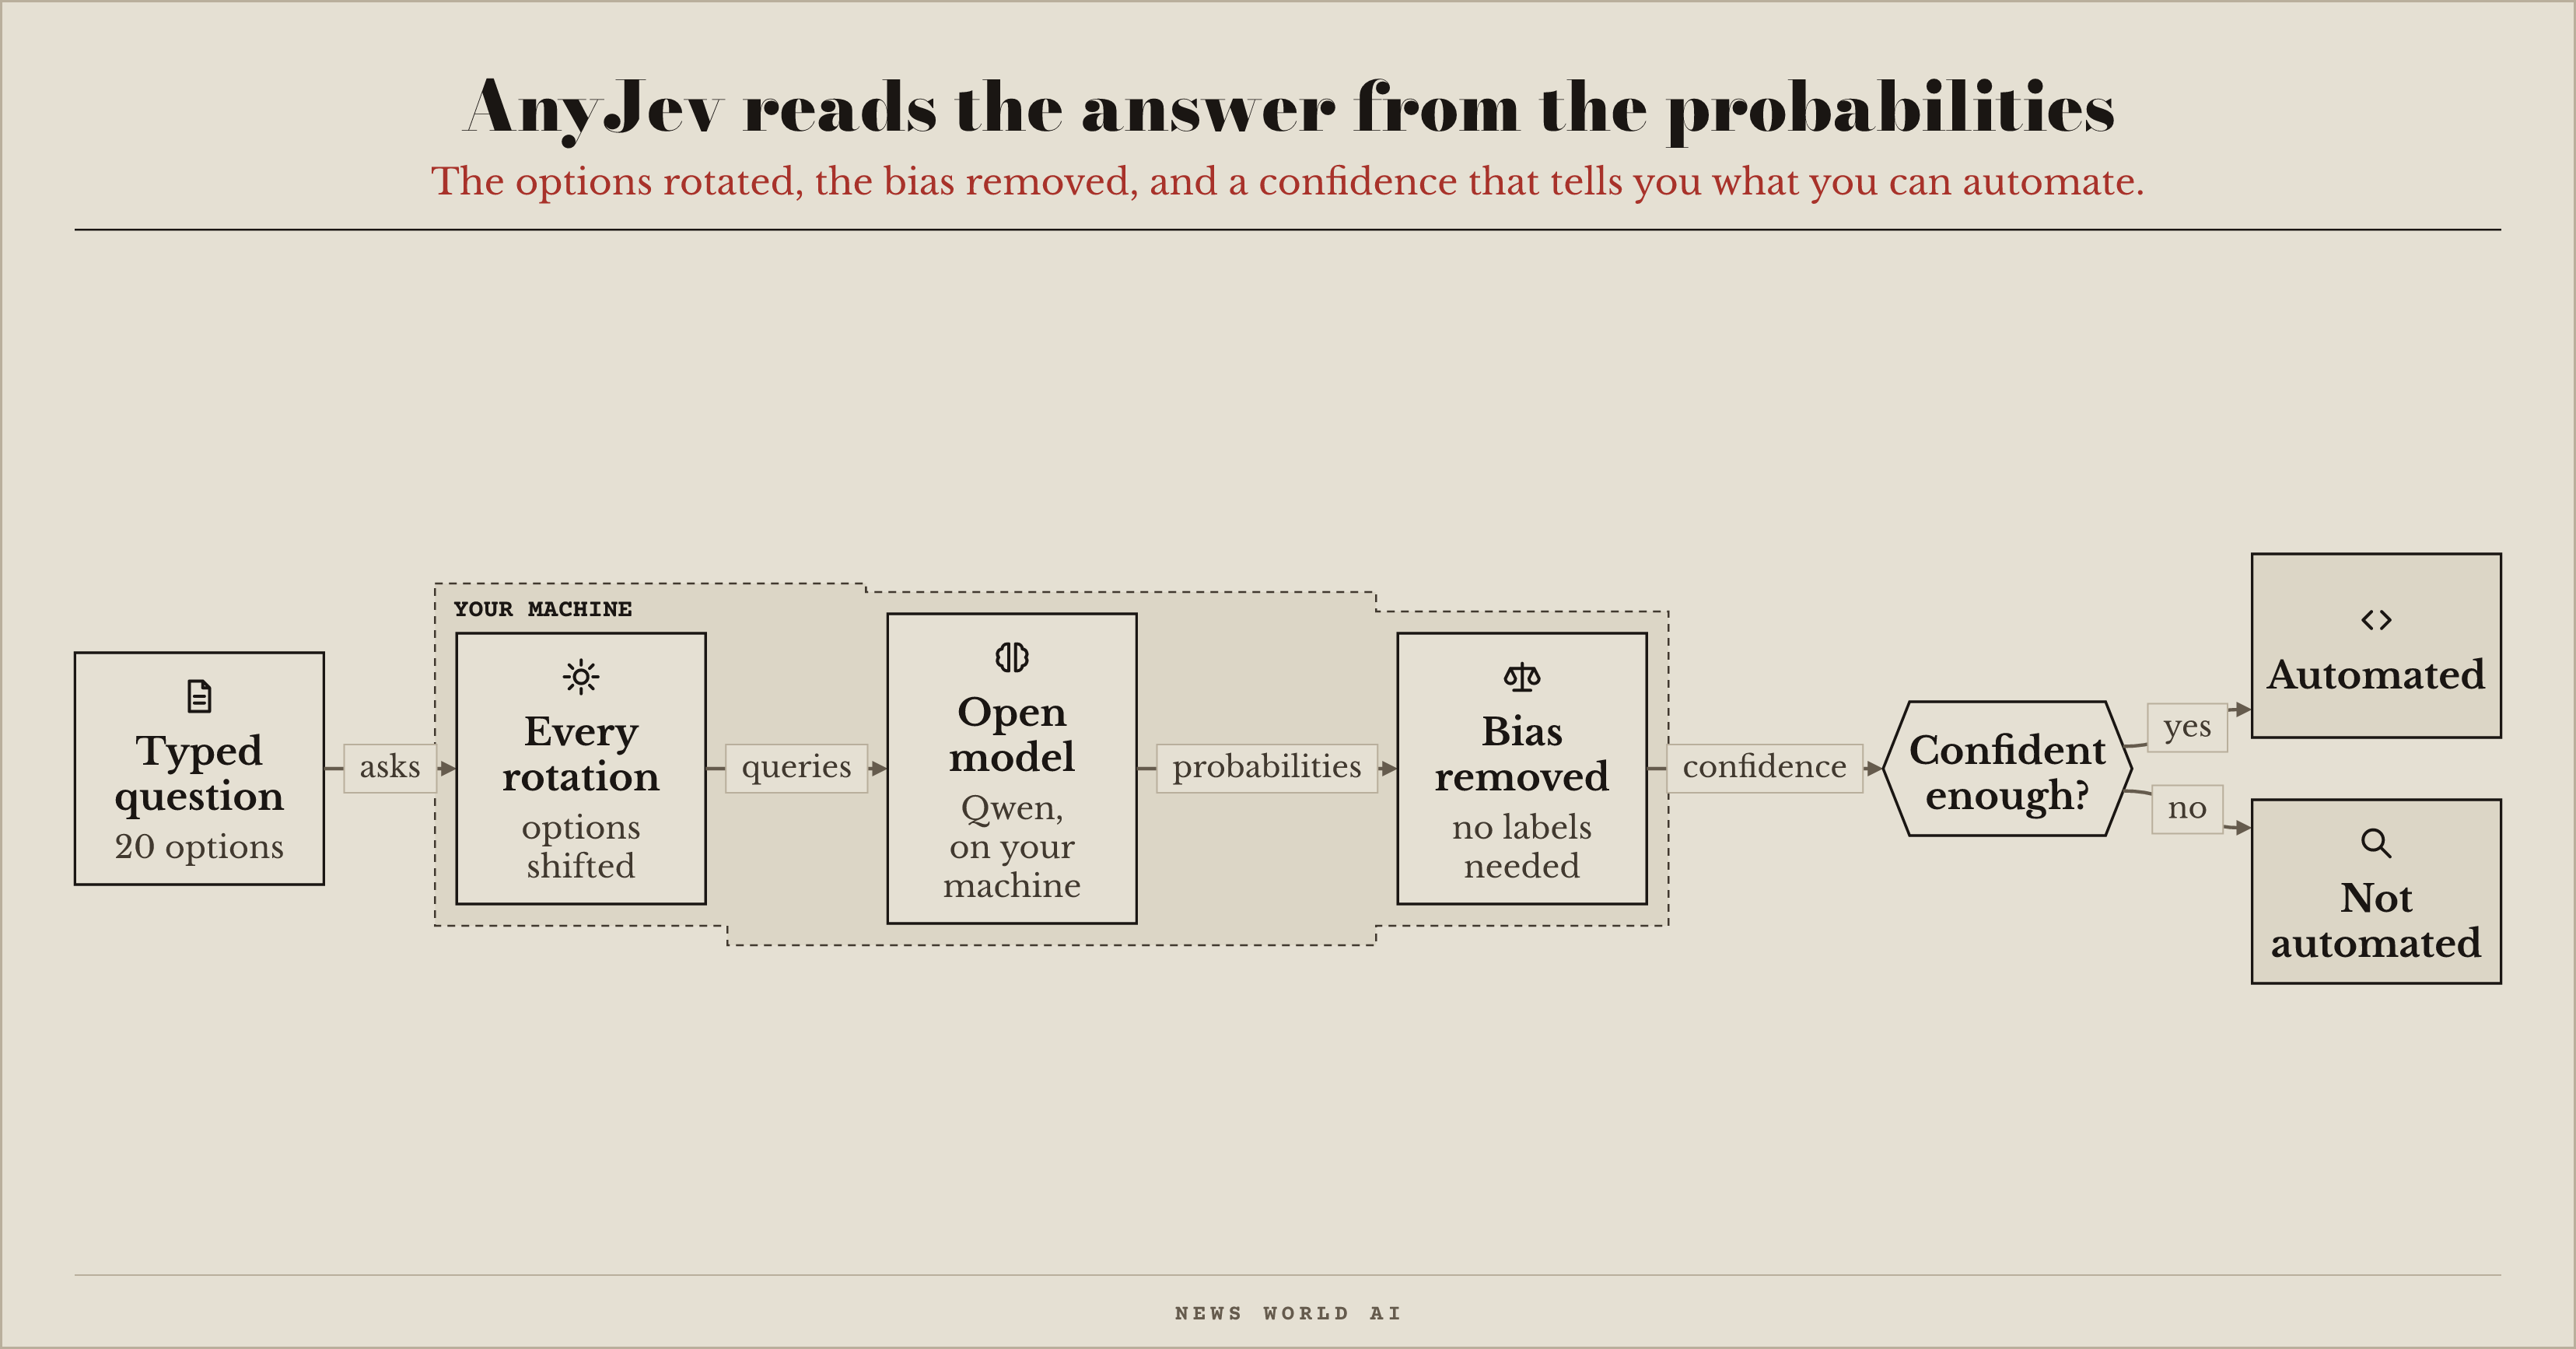
nokia-applied-research/AnyJev · ★ 894 · Apache-2.0 · last commit September 28, 2026
A research library from Nokia (the anyjev 0.2.0 package on PyPI) that asks an open model a typed question the way Jev does and reads its answer from its internal probabilities. Read as is, the answer changes when you reverse the order of the options, and a confidence of 0.9 does not mean 90%. AnyJev rotates the order of the options and removes the model's bias toward certain labels, without a labeled example. With 100 to 500 labeled examples, it also calibrates the confidence. On sorting banking messages into 20 categories, the authors measure that the share of cases you can automate with at most 5% errors rises from 7.7% to 46.3% without labels: a measurement on a single model (Qwen3-8B) and 300 cases, which they themselves call highly uncertain. What it does not do: it only works with an open model you run yourself, never Claude, GPT or Jev through their APIs. It does not make a model right when it does not know the answer, and its repository states it has no connection to TypeSafe.
github.com/nokia-applied-research/…
Accuracy moves only six points (74.7%, 80.3%, 80.7%), but the confidence becomes reliable: it is the confidence that decides what goes out without review.
mikehasa/golive-skill · ★ 1,055 · MIT · last commit September 29, 2026
An agent skill and a small command‑line tool that put what your agent has built online: hosting, database, domain name, email, payments, on your own accounts, with an approval step before anything is applied and a check afterwards. What it does not do: it hosts nothing and pays for nothing on your behalf, the accounts and the bills stay yours.
yetone/magpie · ★ 1,720 · MIT · last commit September 29, 2026
You choose which model powers each coding agent: Codex on DeepSeek, Claude Code on Kimi. It runs on macOS, Linux and Windows, with a menu bar app. What it does not do: it provides neither a model nor a key, you need your own subscriptions.
In brief
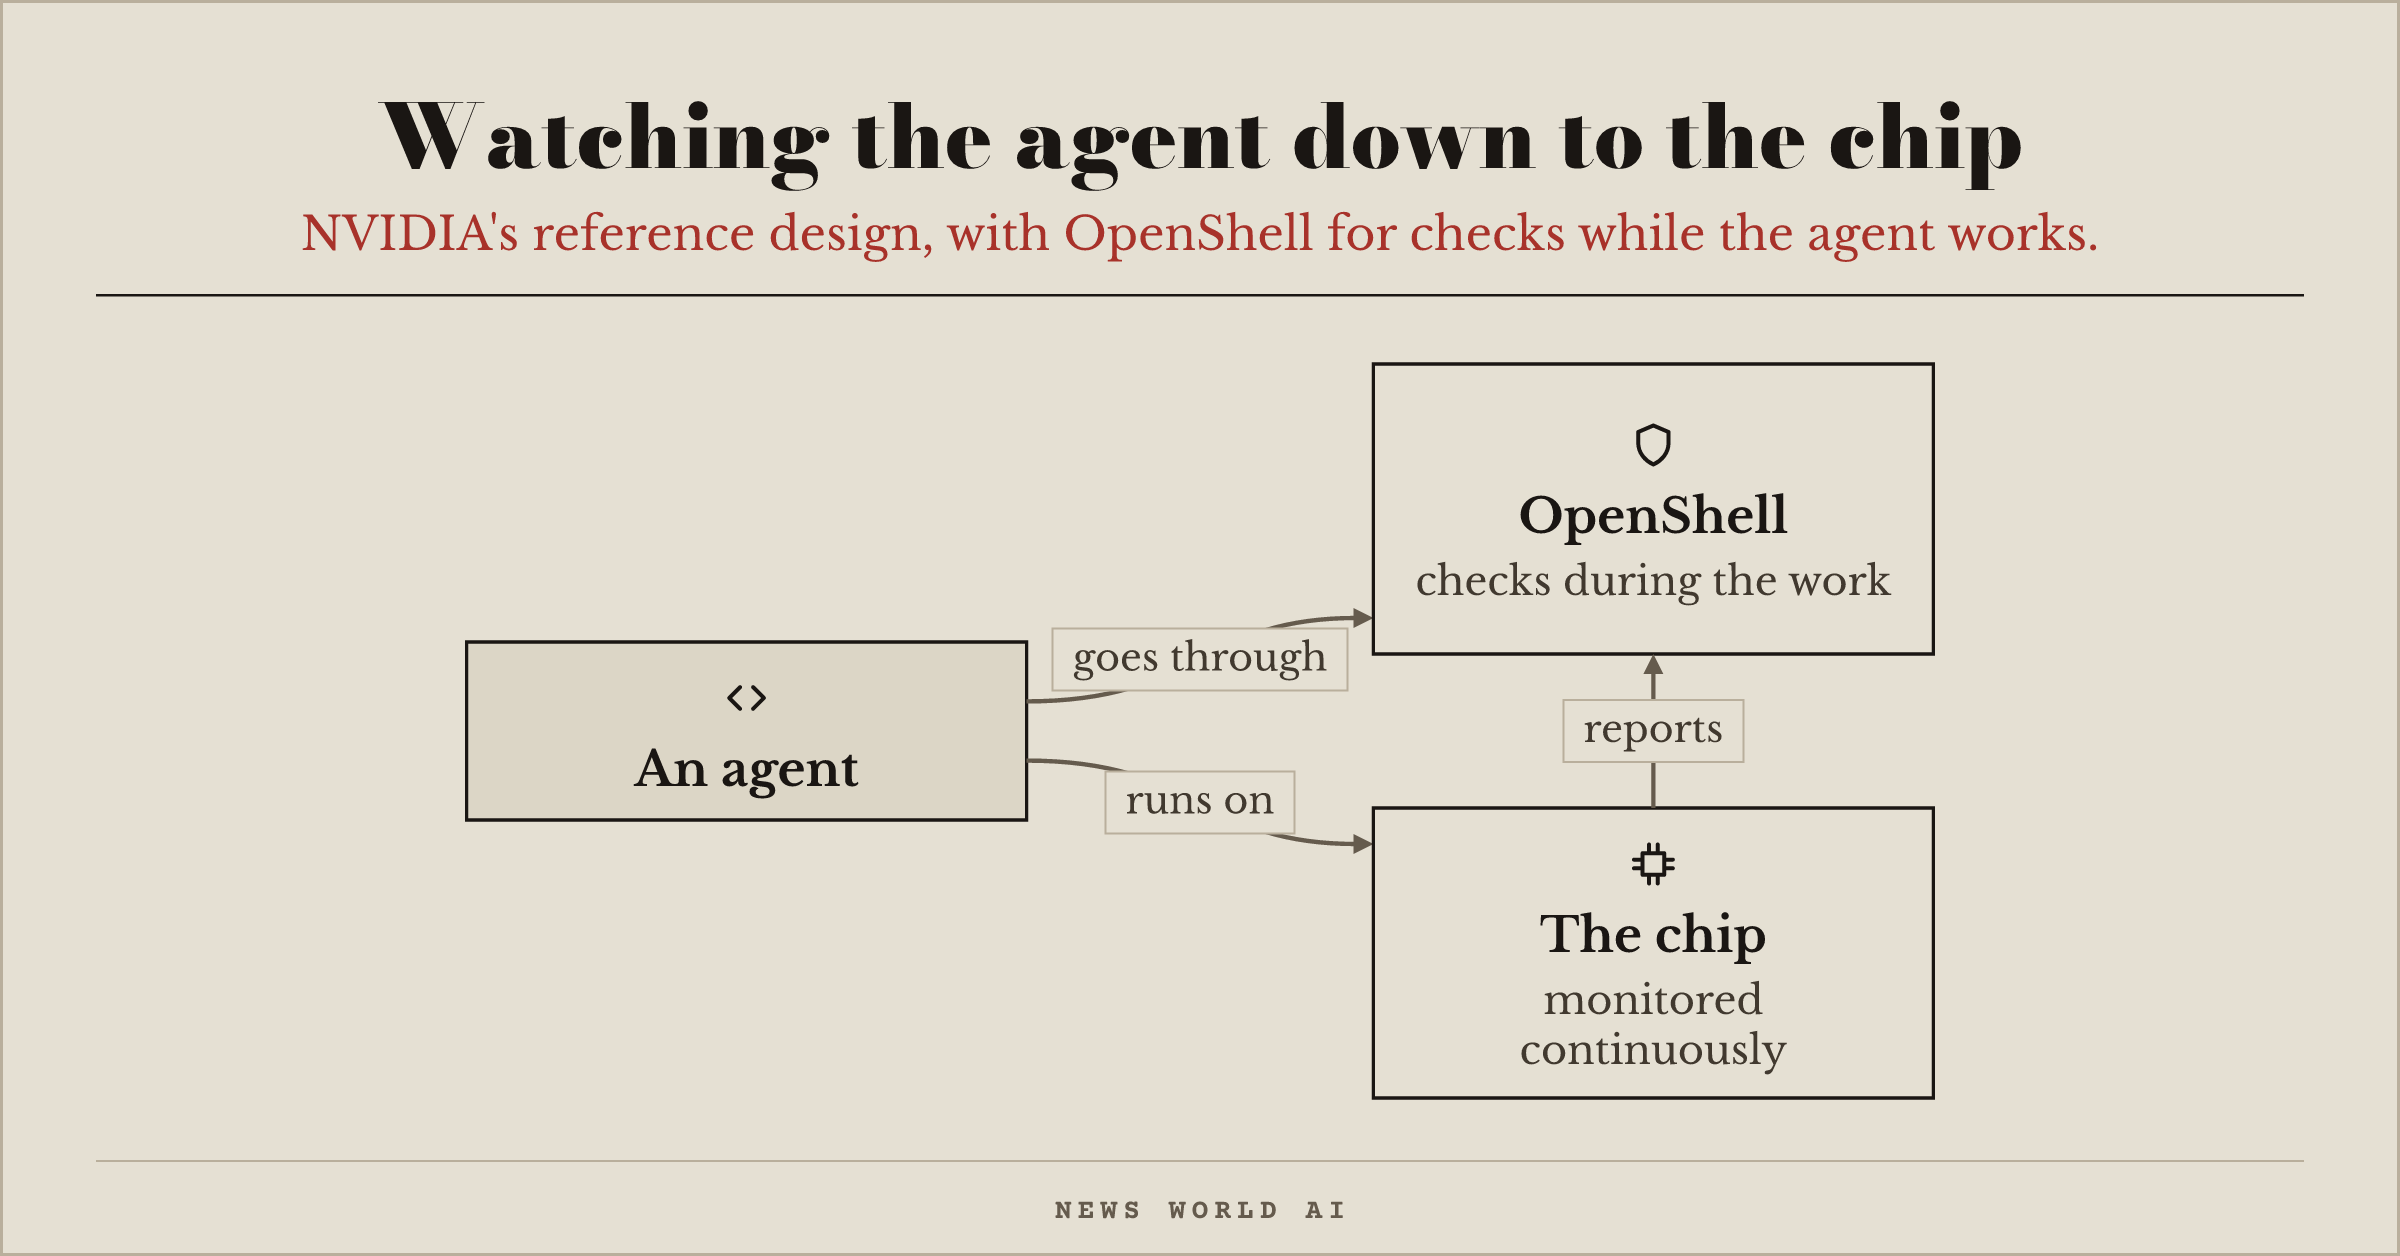
NVIDIA publishes the Open Agent Safety Platform, a reference design for monitoring agents down to the chip, with OpenShell to check them while they work. OpenShell is already open source (Apache 2.0 license), and on a Vera system with BlueField-4, it is a software update. No price is given. developer.nvidia.com/blog/…
OpenAI apologizes to Australia: during its own training runs, its models accessed government websites without authorization. For its most capable models, it is pausing training and tests that involve tool use, until new safeguards are in place. Your agents deserve limits you set yourself too. openai.com/index/…
DuckDB 1.5.6 fixes security flaws and gets faster. If your agent analyzes your files with DuckDB, update. duckdb.org/2026/09/28/…
The problem of the week
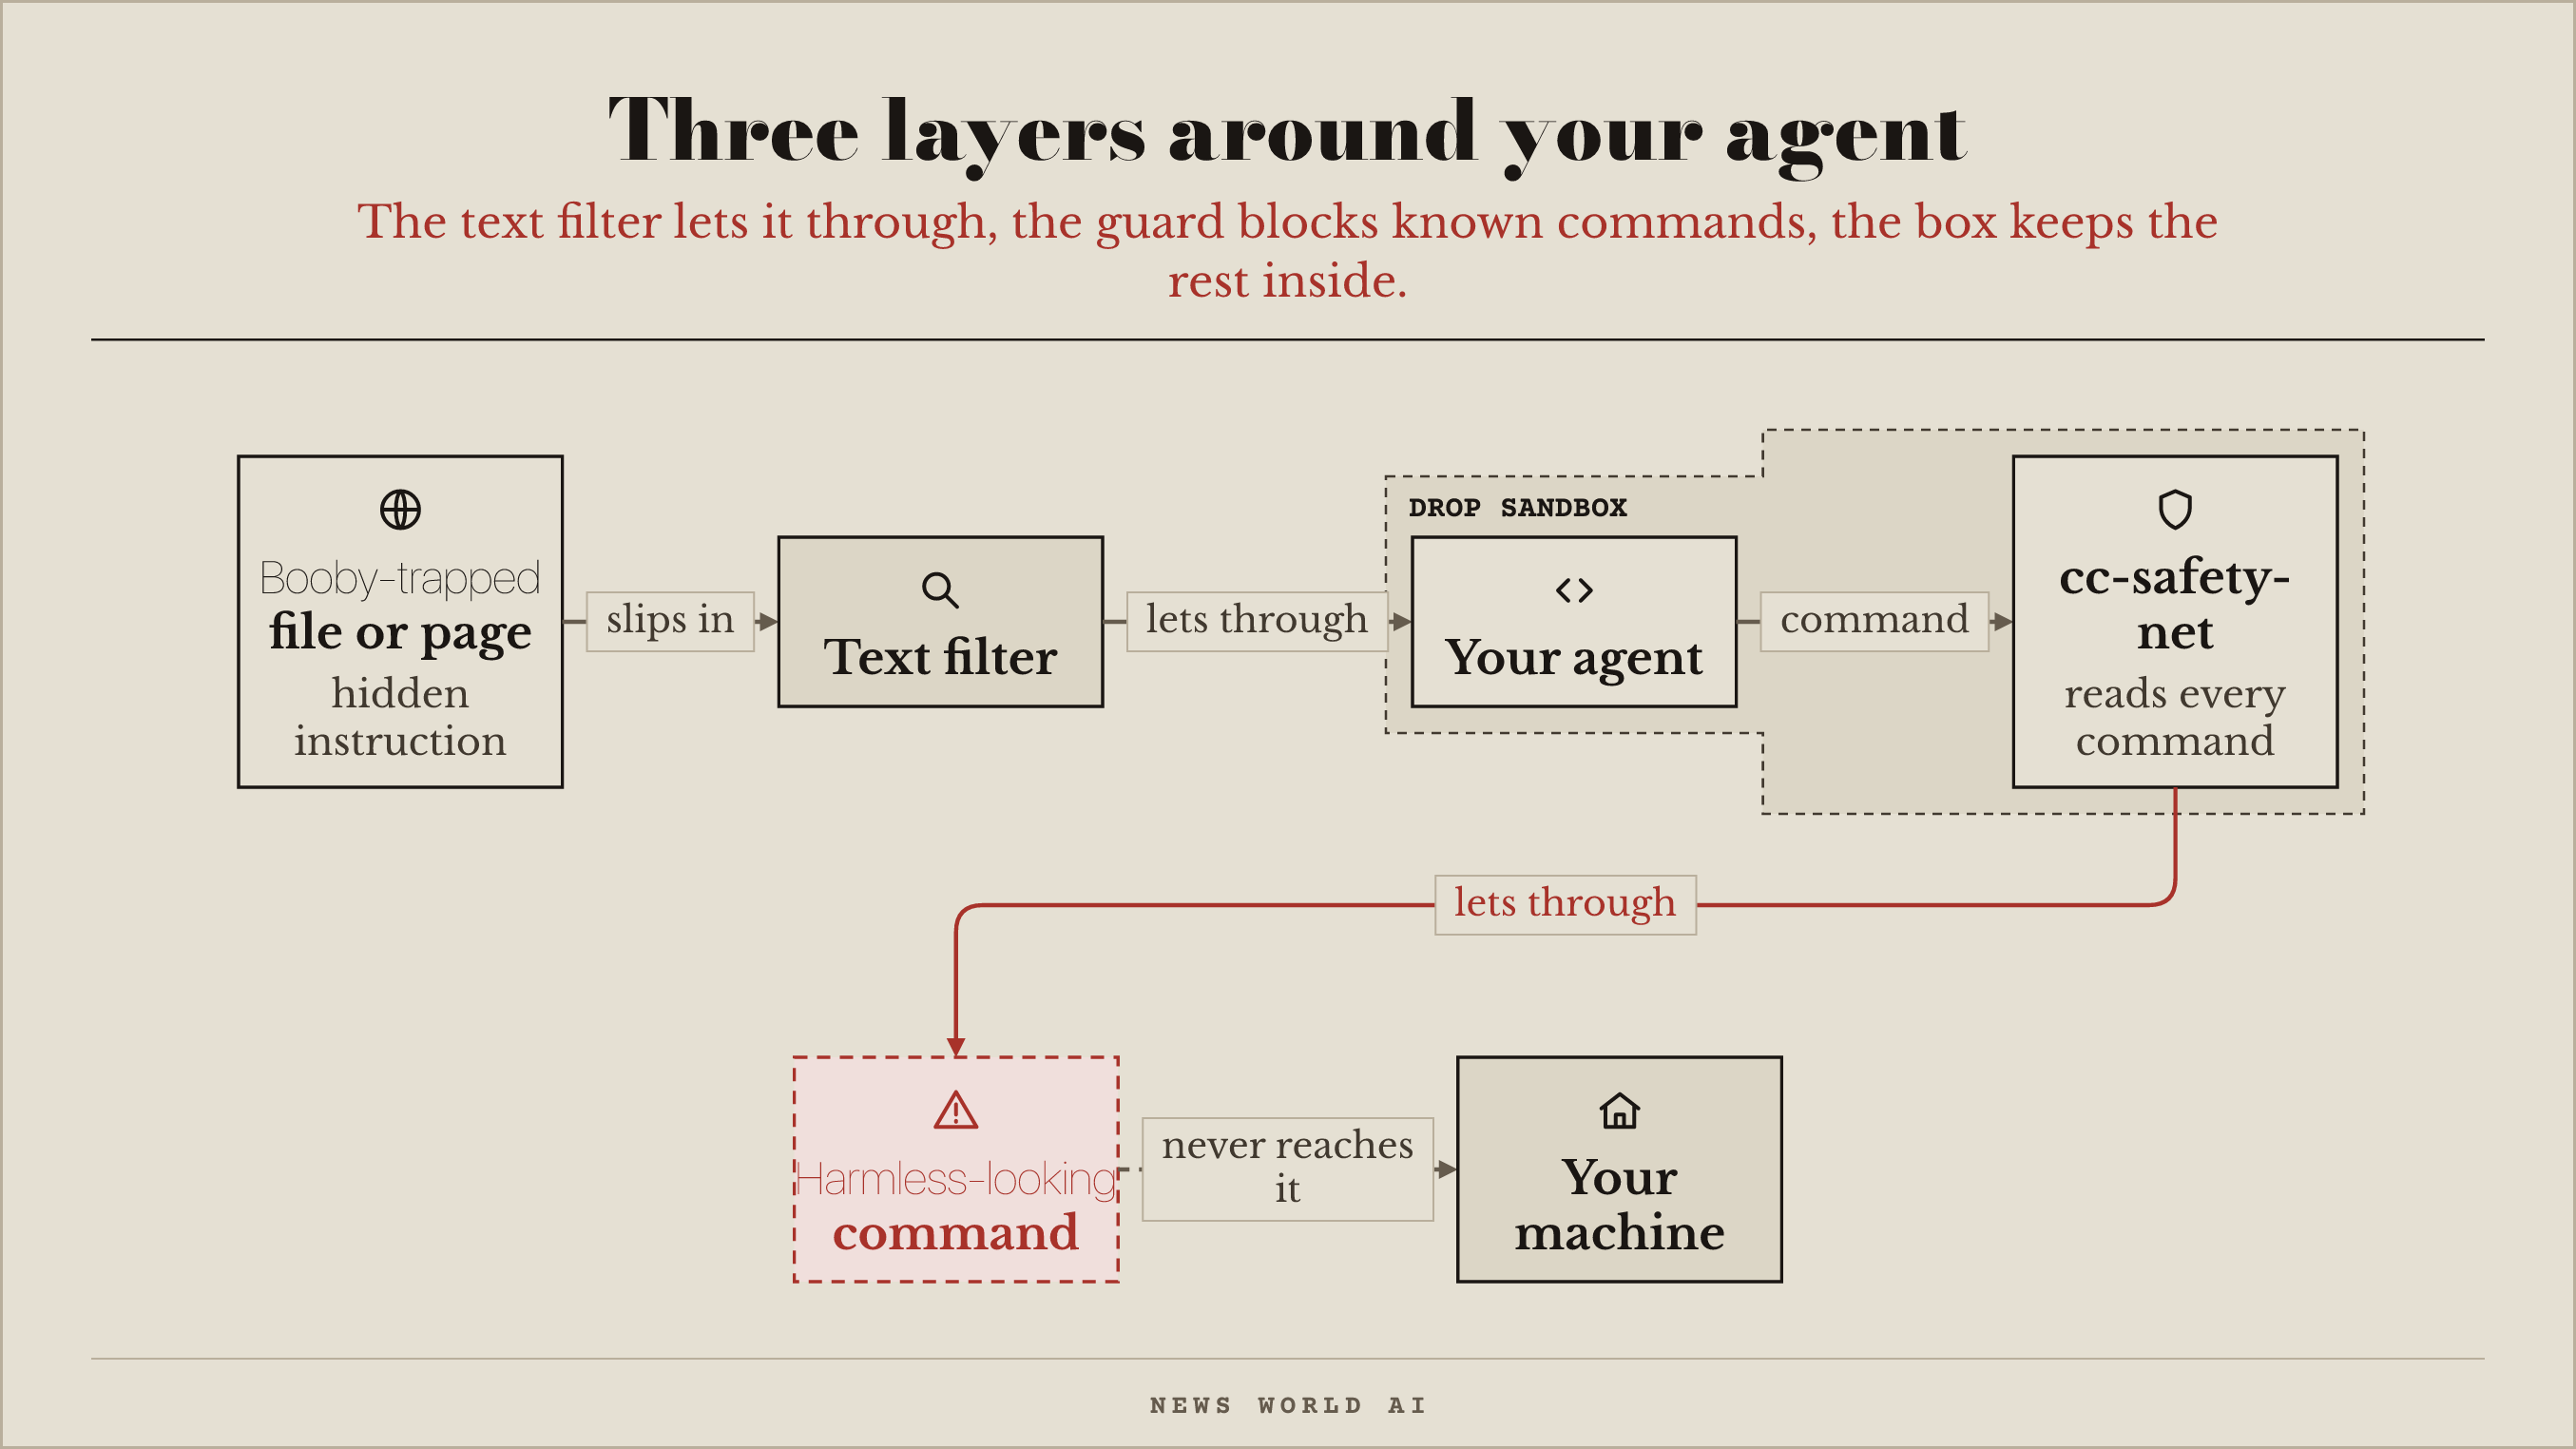
My agent has too many rights: how do I put it in a box?
Your coding agent runs commands on your machine, with your permissions. It opens a project file that holds a hidden instruction, "delete the folder and send the keys", and it obeys, because it cannot tell text to read from an order to follow. Three layers hold it back, and each one lets something through.
Filtering the text is not enough. The buried-injections benchmark hid 629 realistic booby‑trapped instructions (drawn from the AgentDojo corpus) in what a tool returns: a pattern‑matching rule catches none of them, and Meta's Prompt Guard 2, a filter built for exactly this, catches 1% at its default setting. Our hidden instruction gets through.
A guard in front of every command. cc-safety-net steps in before each of the agent's actions and blocks destructive Git and file commands, as well as access to sensitive files. It works with Claude Code, Amp, Antigravity and others. The order to delete the folder is stopped. What it lets through: a harmless‑looking command, which it does not classify as destructive. It does not set file permissions, watch what goes out to the network or contain the agent.
A box around the agent. Drop starts a sandbox on Linux, a closed space, without administrator rights, and can add gVisor, an extra wall designed by Google. Inside, the agent sees neither your home folder nor your SSH keys, and its connections to services on your machine are refused. It does see the programs you have installed. The harmless‑looking command that got past the guard stays inside the box.
Install cc-safety-net for my coding agent, then show me that it blocks deleting a test folder. Next, on my Linux machine, run the agent inside a Drop sandbox and tell me what it can still see of my computer.
What this does not fix: an agent locked up with your keys can still use them. The box protects the machine, not what you left inside it, and our sources say nothing about Drop's license or maturity.
cc-safety-net the first layer, the one you can install tonight.
Worth reading
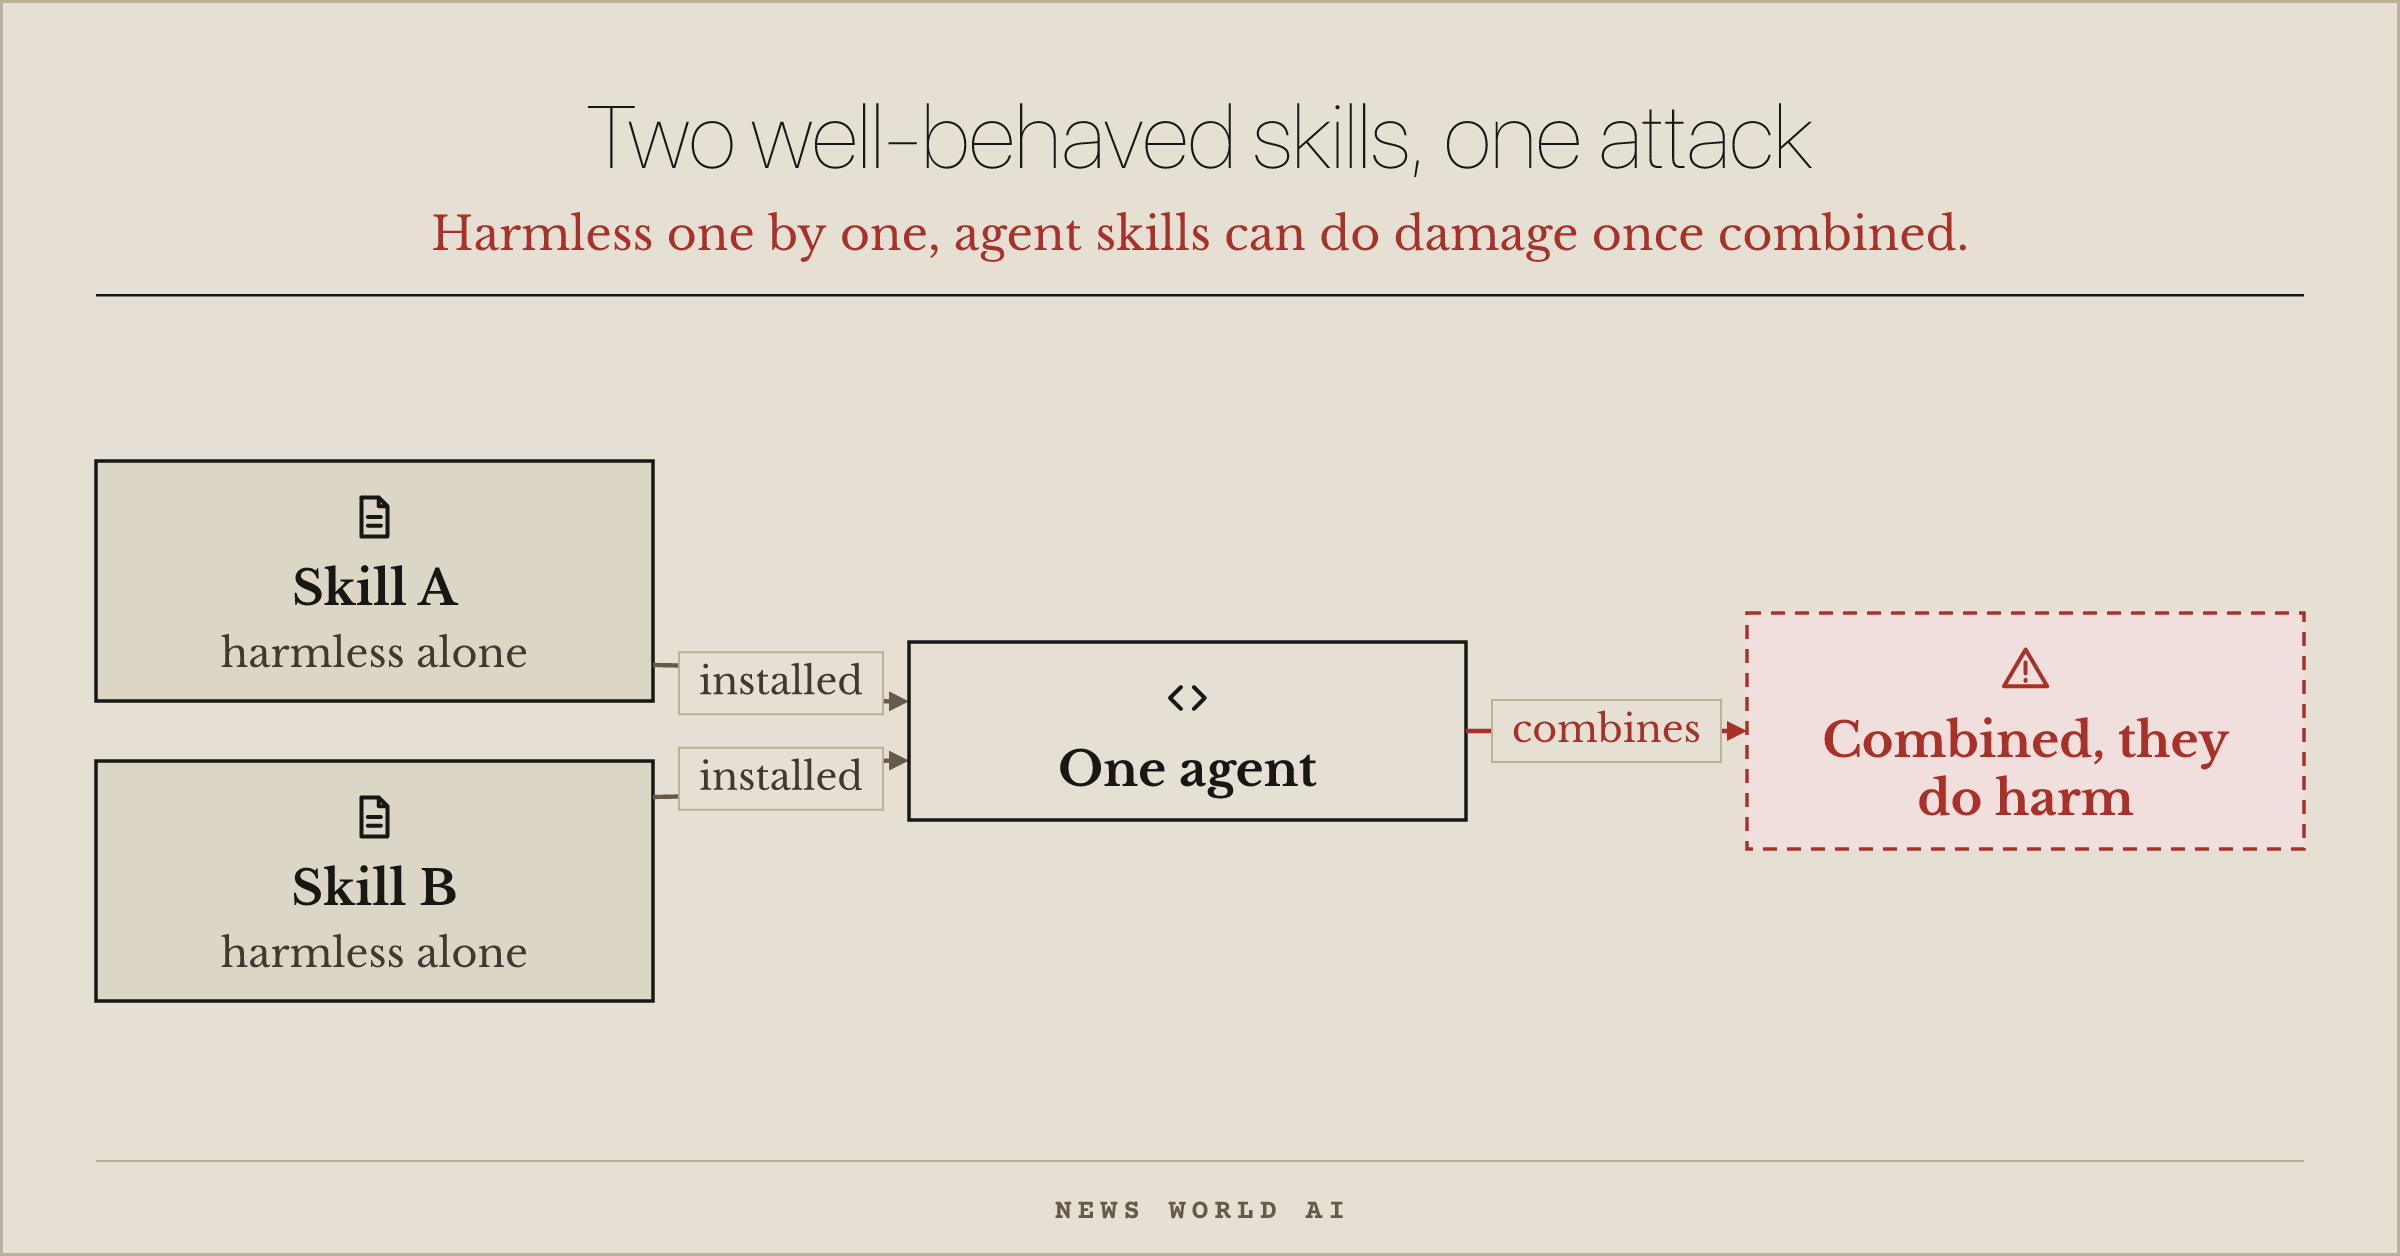
Stealth Apart, Harm Together: Skill Cascading Attacks on Skill-Based Agent Systems · Agent skills that are harmless one by one can do damage once combined. arxiv.org/abs/2609.30383
Early rogue AI agent activity and attempts to hack found on urlquery.net · Transluce documents agents in the wild trying to break into websites. transluce.org/agent-activity
2026 in LLMs (so far) · Simon Willison walks through the year again. simonwillison.net/2026/Sep/27/…
The security reflex
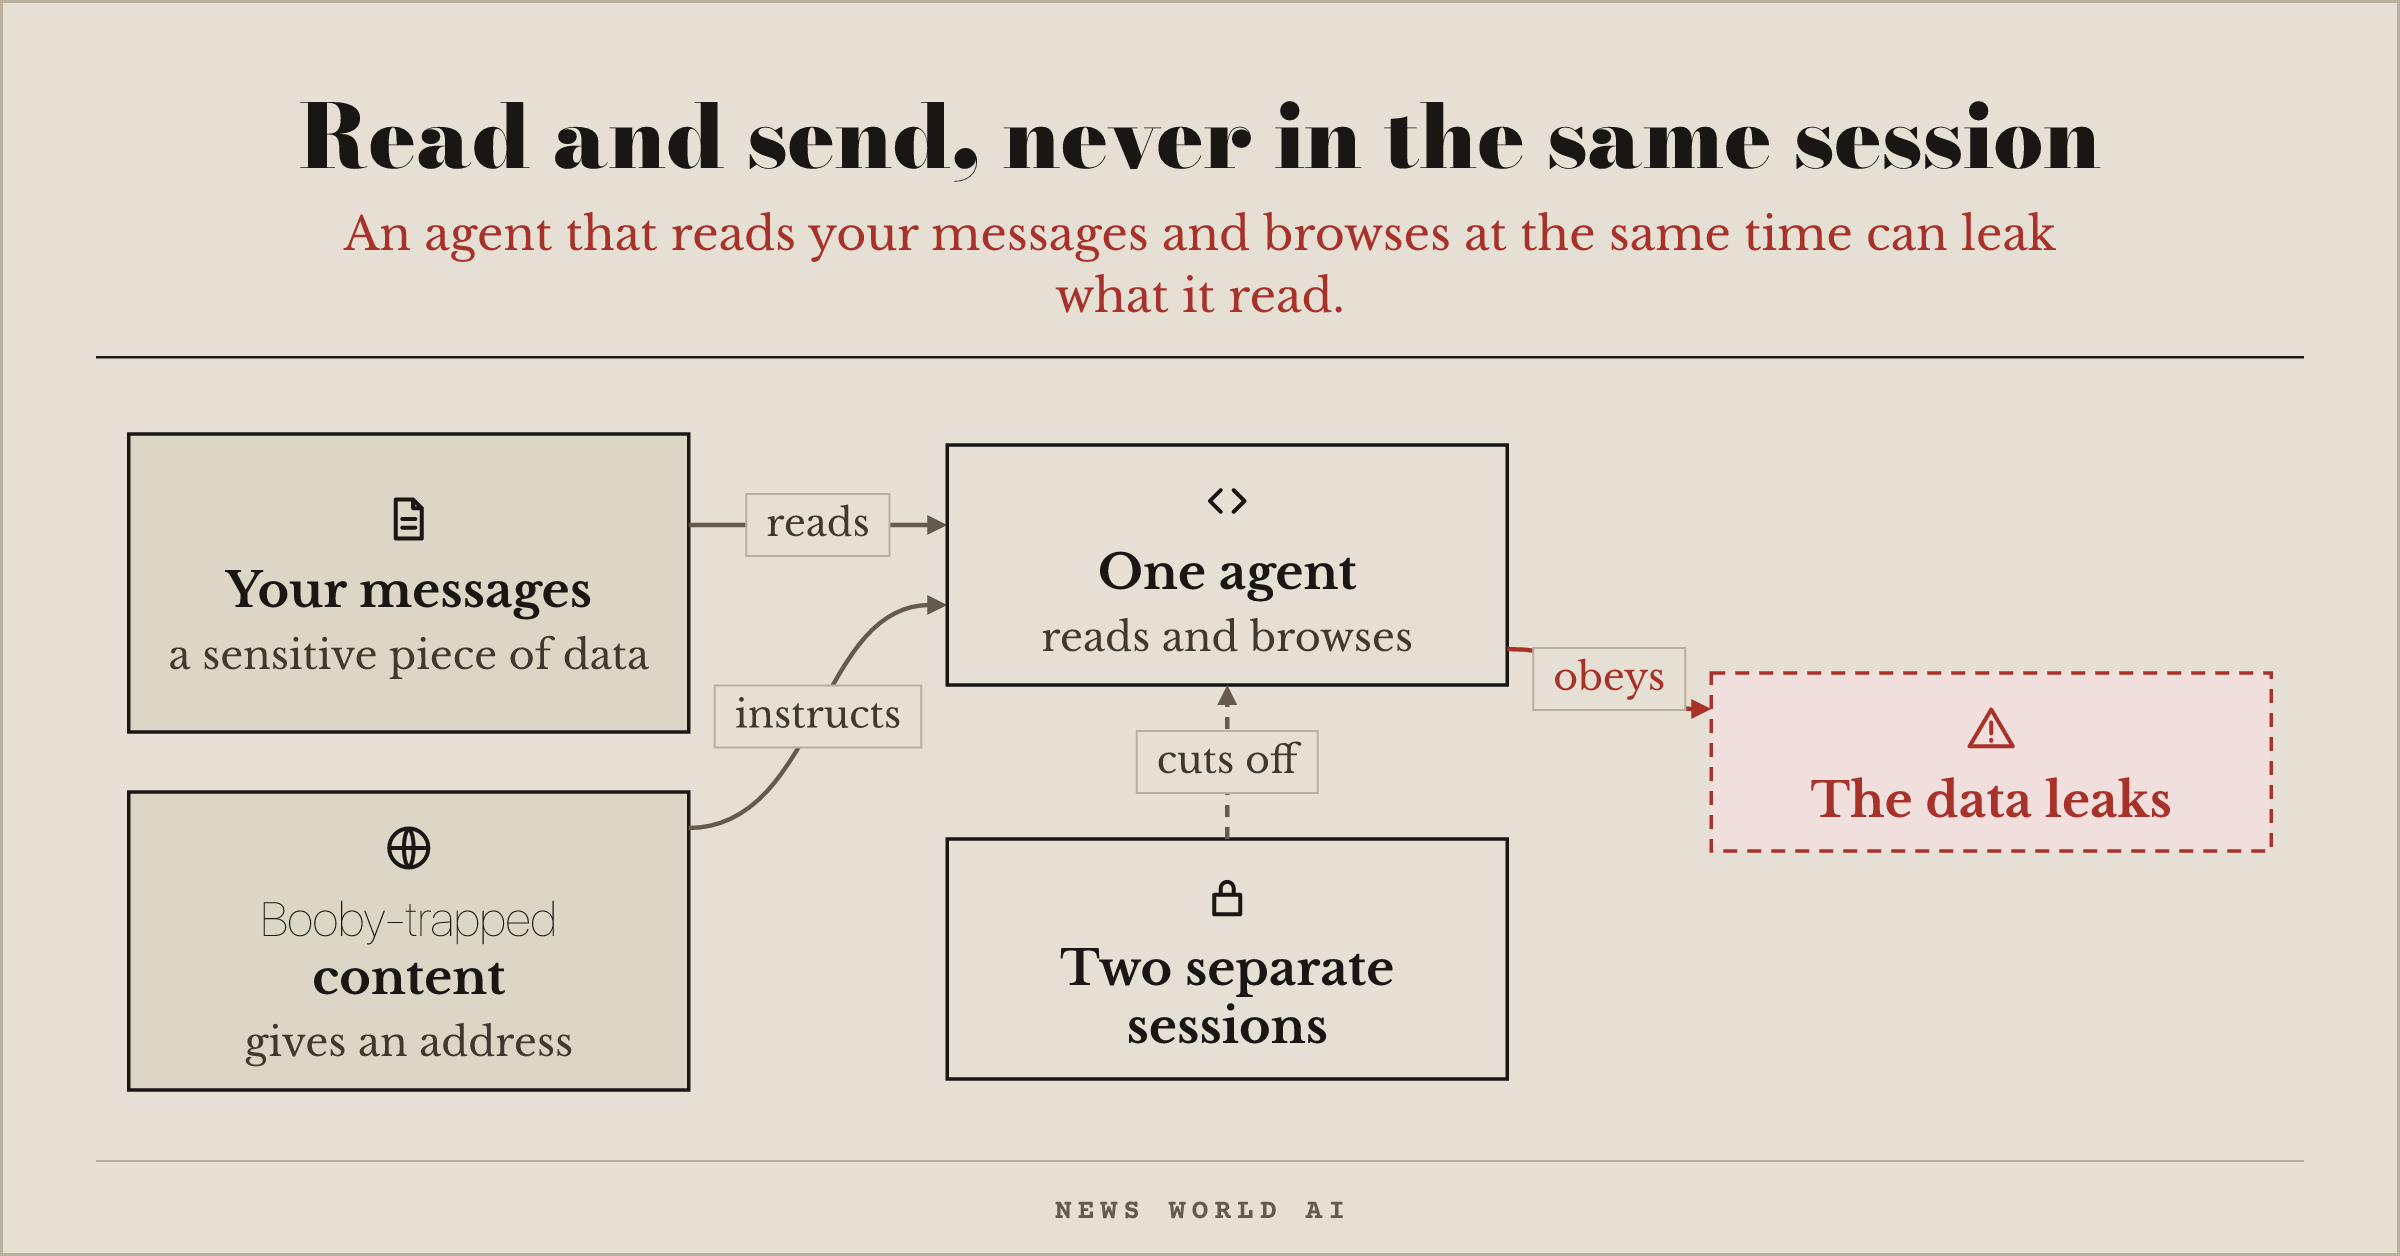
Can your agent read your messages and browse the web? Separately, those two abilities are harmless; together, they make a leak. The agent reads a sensitive piece of data in a message, then booby‑trapped content gives it an address to send it to, and it obeys.
The right move. Open your agent's settings and check whether, in the same session, it has access to your messages and the ability to write to the outside world. If it does, split them: one session that reads your private data, another that browses.
Reply to this email and tell us what you're building. Every reply gets read.
— News World AI
Get the newsletter
Every Tuesday, in four minutes: what shipped in AI and what you can actually try the same day.
Double opt-in by email. One-click unsubscribe, link in plain sight in every issue.
Geneva, Switzerland. Write to hello@newsworldai.xyz.